
COMPETITOR COMPARISON
Requesty Alternatives By Operating Responsibility
Evaluate Requesty for routing control, compatibility, observability, and operating cost.
Published: · By the QVeris Team
TL;DR
Its documentation highlights an OpenAI-compatible endpoint, hundreds of models, fallback, caching, analytics, load balancing, BYOK, guardrails, and access controls.
The service owns availability and upgrades; your team still owns routing intent, budget policy, provider contracts, and application failure behavior.
A common API speeds switching, but model-native capabilities and error semantics can still leak through the abstraction.
It complements an LLM router when agents must discover and invoke data sources and tools.
Define what “managed routing” must own
Health checks, provider failover, retry safety, regional incidents, status communication, and recovery objectives.
Provider price, intermediary fees, caching savings, failed-request charges, commitments, budget enforcement, and invoice reconciliation.
Identity, tenant isolation, model allowlists, guardrails, key custody, audit exports, retention, and approval workflows.
Timeouts, idempotency, partial streaming, schema validation, fallbacks that change quality, and user-visible degradation.
Eight Requesty alternatives by ownership model
| Option | Primary fit | Ownership shift |
|---|---|---|
| Portkey | Managed gateway with deep policy and observability | Broader platform evaluation |
| Vercel AI Gateway | App teams using Vercel and AI SDK | Closer platform affinity |
| Cloudflare AI Gateway | Edge-native routing and analytics | Edge platform becomes control boundary |
| OpenRouter | Model marketplace and broad LLM access | Procurement model changes |
| LiteLLM | Self-hosted, configurable multi-provider proxy | Operations move to your team |
| Bifrost | High-throughput focused data plane | Control-plane design moves to your team |
| Kong AI Gateway | Enterprise API platform reuse | More platform administration |
| Direct provider APIs | Native features and direct contracts | All routing and reliability return in-house |
Calculate the cost of the whole request
Model price is only one line. Add platform or plan fees, any intermediary charge, cache storage, data transfer, observability retention, support, failed and retried requests, and engineering time. Then subtract measured cache hits and operator hours avoided. Because published terms can change, attach a date and source to every price assumption rather than repeating an undated percentage.
A five-failure proof test
- Throttle the primary provider and confirm route choice, retry count, latency ceiling, and budget impact.
- Break a streaming response after partial output and observe whether the client can recover safely.
- Return malformed structured output and verify validation, repair policy, and attribution.
- Rotate and revoke a provider key while active requests are running.
- Lose telemetry export and prove requests remain safe while evidence loss is alerted.
Pass condition: every failure has an expected owner, bounded user impact, traceable routing decision, and reconciled cost.
Migrate policies before endpoints
Export routes, weights, fallback order, cache rules, keys, model aliases, budgets, guardrails, tenant mappings, dashboards, and retention settings. Express them as a versioned traffic contract. Shadow requests to the candidate without serving output, compare model selection and telemetry, then canary one tenant. Keep an application-level bypass until provider errors and invoice totals reconcile.
Add a governed capability layer after routing
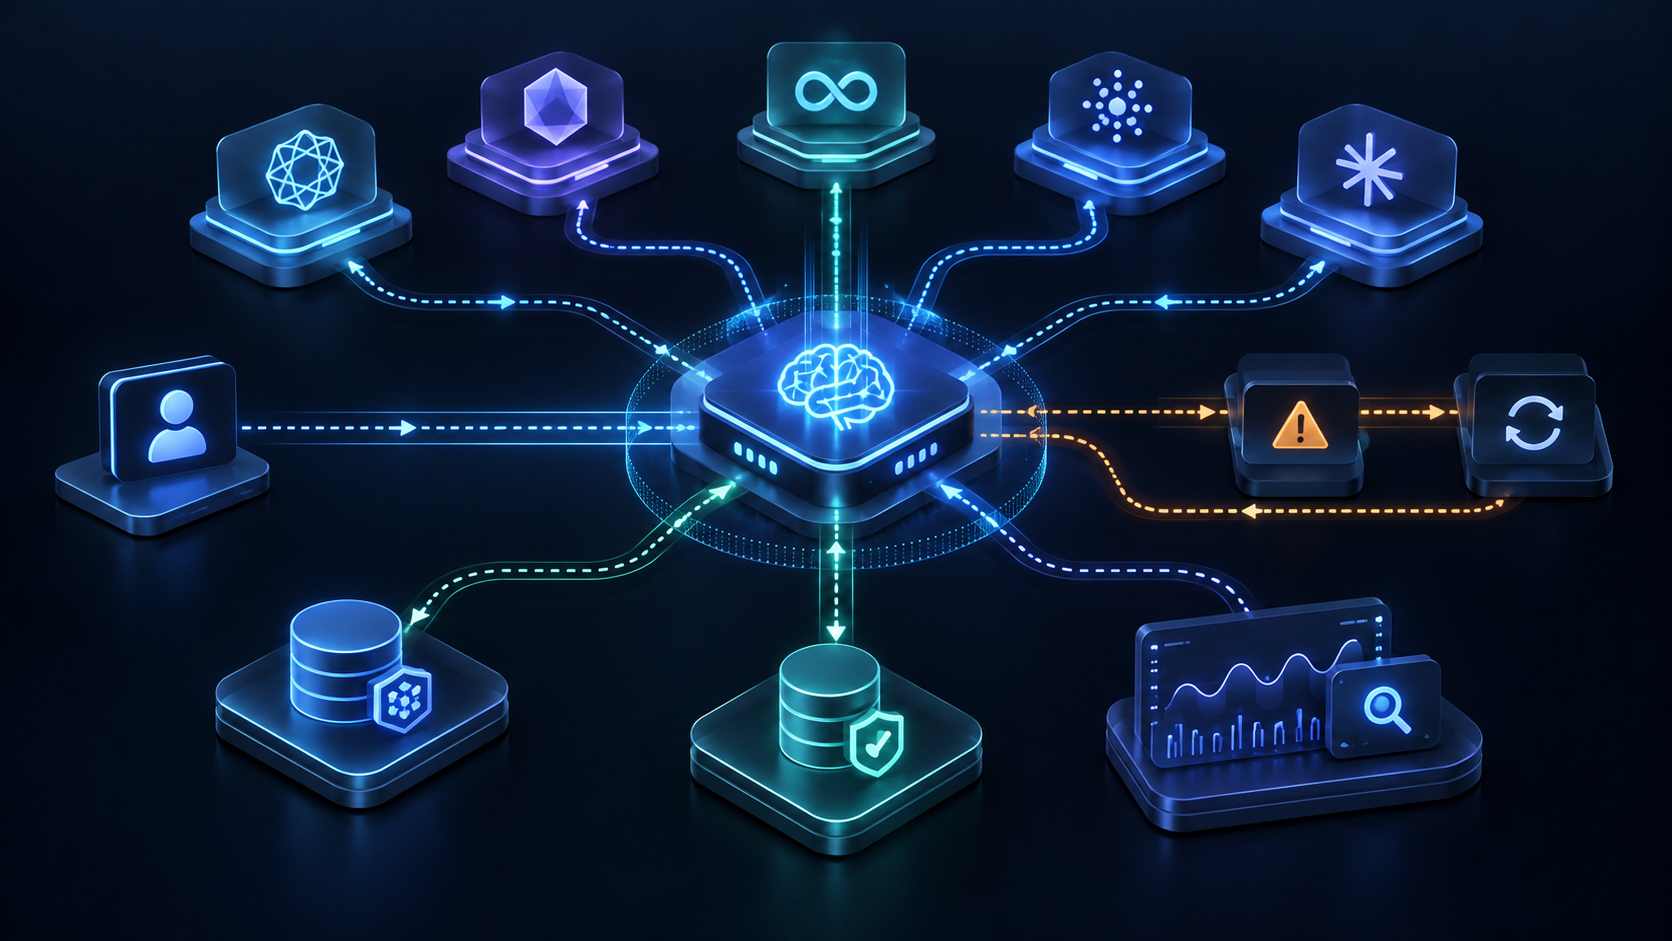
Requesty or another gateway selects and calls a model. QVeris helps the resulting agent discover a data source, API, or tool; inspect its contract; invoke it with controlled credentials; and preserve evidence. One trace context should span inference, routing, and tool execution.
Continue with related implementation guides
Use these adjacent guides to compare the next architectural decision, implementation boundary, or operating control without starting the research again.
FAQ
It provides broad model access, but evaluate whether your intended flow uses platform-provided access, BYOK, or direct provider contracts.
LiteLLM and Bifrost are focused candidates. Ease depends on identity, telemetry, upgrades, scaling, and incident ownership—not installation alone.
Yes for repeatable workloads, but measure semantic correctness, privacy boundaries, invalidation, storage, and cache fees.
No. QVeris is a complementary external capability layer, not a multi-model inference router.