
COMPETITOR COMPARISON
Unify AI Alternatives: Teammates vs LLM Routers
Assess Unify AI across routing control, compatibility, observability, and operating cost.
On this page
TL;DR: choose the category before the vendor
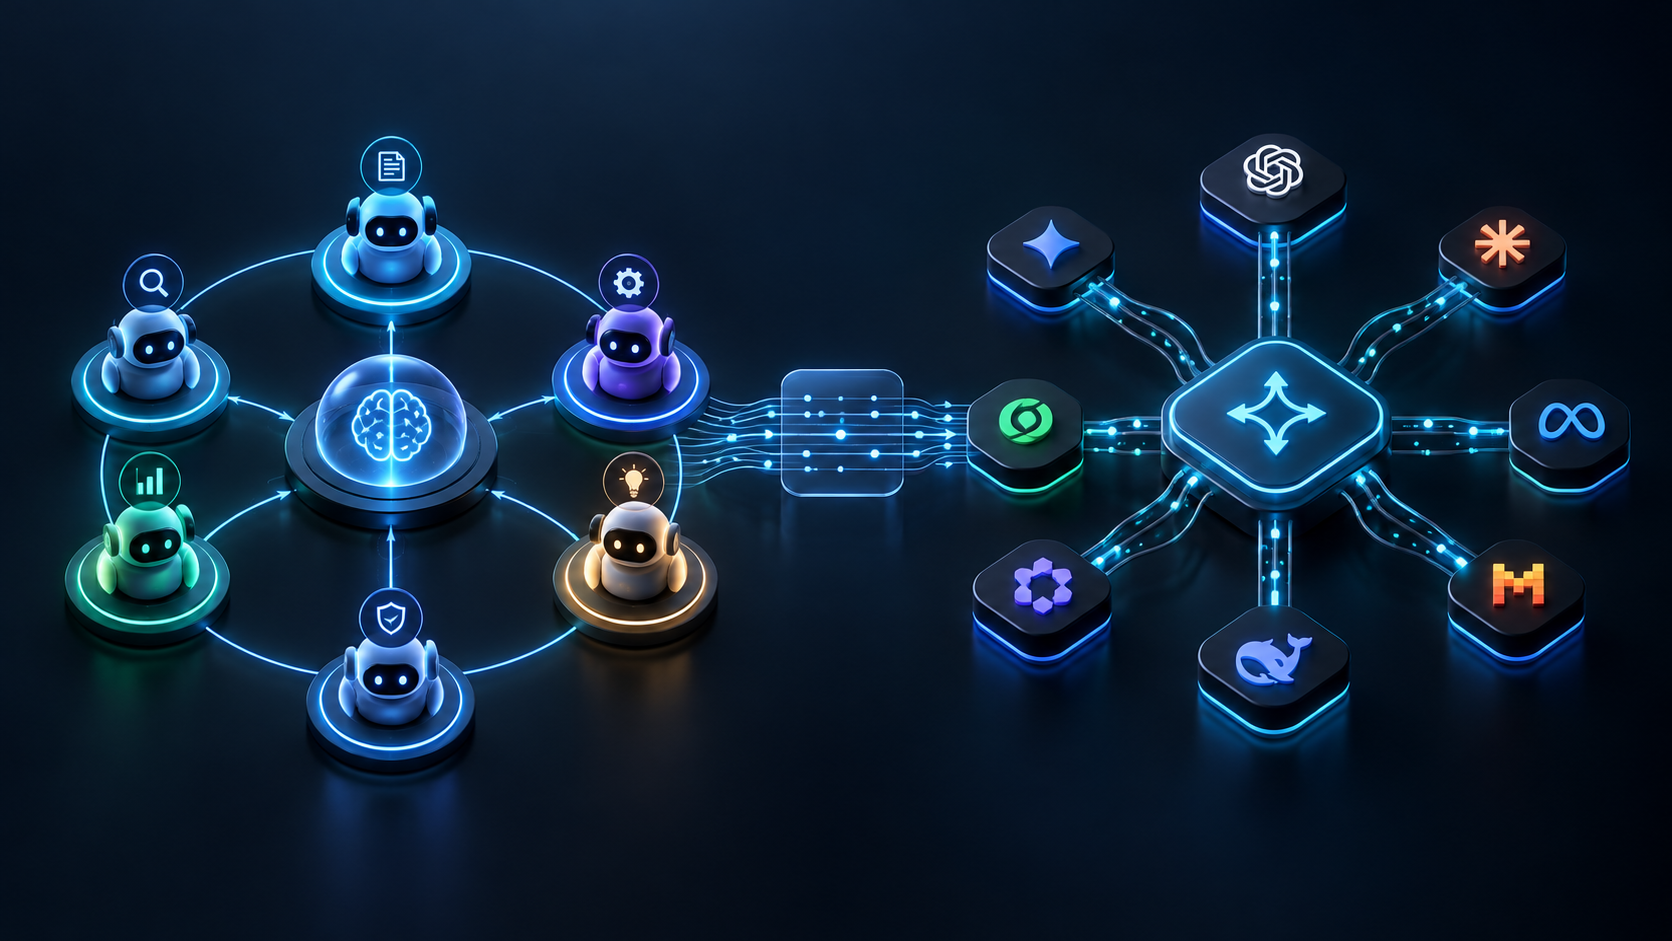
If you want an AI coworker that watches channels, remembers context, runs scheduled work, uses business tools, and asks for approval, compare Unify with Lindy, Relevance AI, Microsoft Copilot Studio, and Glean Agents. If you want one API for model routing, failover, budgets, and observability, compare the historical Unify intent with LiteLLM, Portkey, OpenRouter, Kong, Cloudflare, Vercel, Bifrost, and Helicone.
The outcome is completed business work across email, CRM, documents, meetings, chat, and recurring schedules.
Your application already owns the workflow and needs reliable, governed access to multiple inference providers.
Why “Unify AI alternatives” contains two search intents
Older descriptions of Unify focused on selecting and routing language models. The current product presents configurable AI teammates that work across channels and applications. Those are different buying decisions, operating models, and migration paths.
| Question | Current AI teammate intent | Historical LLM router intent |
|---|---|---|
| Unit of work | Task, workflow, conversation, scheduled job | Model request, stream, embedding, tool call |
| Primary buyer | Operations, sales, support, knowledge, business teams | Platform, infrastructure, application, ML teams |
| Success metric | Correct completion, approval safety, time saved | Availability, latency, cost, policy compliance |
| Migration artifact | Instructions, memory, integrations, schedules, approvals | Base URL, model aliases, keys, routes, logs, error contract |
Who this guide is for—and who should skip it
You need recurring work across SaaS tools with clear ownership and human approval.
You care about identity, permissions, publishing, auditability, environment separation, and lifecycle controls.
You already own orchestration and need a gateway for providers, keys, budgets, fallbacks, and telemetry.
You only need a single model SDK, a basic chatbot, or a deterministic two-step automation with no agent behavior.
Evaluation method and evidence rules
This guide separates official product claims from buyer verification. A feature receives credit only when it can be connected to an official page and reproduced in a test workspace. Marketing copy alone is not acceptance evidence.
- 1Define the outcome.Write what must be completed, not which feature must exist.
- 2Freeze the workload.Use identical inputs, permissions, deadlines, approvals, and failure injections.
- 3Capture raw evidence.Keep run IDs, timestamps, prompts, actions, outputs, errors, usage, and human interventions.
- 4Score after testing.Do not turn an unchecked feature matrix into a winner.
Establish the current Unify baseline fairly
The current Unify baseline is broader than “an agent builder.” Official pages describe teammates that can operate across channels, run scheduled work, use integrations, preserve memory, collaborate, and receive private task machines. Its pricing is workspace credit based, with features included across plans and enterprise controls handled separately.
| Baseline dimension | What to verify | Why replacement may still make sense |
|---|---|---|
| Channels | Chat, email, SMS, WhatsApp, calls, connected workspaces | Your organization standardizes on another ecosystem |
| Proactivity | Schedules, monitoring, follow-up, interruption and steering | You need deterministic flows or stronger lifecycle governance |
| Tool execution | OAuth scope, browser fallback, approval gates, audit trail | Required apps, controls, or data boundaries are missing |
| Commercial model | Credits per task class, reset policy, enterprise terms | Spend is hard to forecast for your workload mix |
Buyer scorecard for AI teammate platforms
| Criterion | Suggested weight | Acceptance evidence |
|---|---|---|
| Task completion quality | 25% | Pass rate over a fixed test set; source accuracy; no silent omissions |
| Action safety | 20% | Least privilege, approval gates, idempotency, reversible actions |
| Integrations and channels | 15% | Required triggers and actions work under production identity |
| Memory and context | 10% | Correct recall, deletion, scope boundaries, stale-memory handling |
| Operations | 15% | Run history, alerts, retries, versioning, test and rollback controls |
| Governance and procurement | 10% | SSO, roles, audit export, DPA, residency, sub-processors |
| Total cost | 5% | Observed cost per accepted task, including retries and human review |
Four current alternatives for the AI teammate intent
Best shortlist fit for trigger-driven business automations with scheduled, event, chat, and multi-agent patterns. Verify connector depth, approval behavior, long-run observability, and cost under your workload.
Best shortlist fit for teams that want configurable agents, tools, knowledge, and multi-agent workforces in a low/no-code environment. Verify governance, test promotion, and connector behavior.
Best shortlist fit for Microsoft-centric organizations that already use Power Platform, Microsoft 365, Teams, connectors, environments, and enterprise administration. Separate generally available capabilities from previews.
Best shortlist fit when permission-aware enterprise knowledge, governed agent publishing, administrator roles, and controlled actions matter more than a broad consumer channel surface.
Decision matrix: which teammate platform enters the pilot?
| Primary requirement | Start with | Prove before buying |
|---|---|---|
| A teammate-like experience across calls, messages, schedules, and business tasks | Unify | Real task completion, approvals, memory controls, credit consumption |
| Fast visual trigger/action automation | Lindy | Connector semantics, retries, duplicate prevention, monitoring |
| Composable agents and multi-agent workforce | Relevance AI | Tool permissions, versioning, evaluation, complex workflow maintainability |
| Microsoft ecosystem and governed environments | Copilot Studio | Licensing, connector policy, environment promotion, preview dependencies |
| Permission-aware enterprise knowledge and controlled publishing | Glean Agents | Source permissions, action governance, scheduled-agent risk controls |
Step-by-step acceptance test for teammate platforms
- 1Connect least-privilege accounts.Use a test Slack channel, a restricted Notion database, and scoped credentials.
- 2Seed a known baseline.Create unchanged, minor-change, and material-change competitor fixtures.
- 3Run manually first.Inspect every source, extraction, comparison, and proposed action.
- 4Test approval boundaries.Reject, approve, time out, and modify a proposed update.
- 5Inject failures.Return 429, 500, malformed HTML, missing permissions, and a slow tool response.
- 6Repeat on schedule.Run long enough to reveal stale memory, duplicates, drift, and credit variance.
- 7Review the evidence bundle.A reviewer must reconstruct why each action happened without opening the builder.
Normalize every run into an evidence contract
A portable evidence record makes vendors comparable and keeps migration possible even when their native logs differ.
{
  "run_id": "cmpwatch_2026-07-31T08:00:00Z",
  "workflow_version": "competitor-watch-v3",
  "sources": [
    {"url": "https://vendor.example/pricing", "retrieved_at": "...", "hash": "..."}
  ],
  "change": {"class": "material", "fields": ["team_price"]},
  "proposed_actions": ["notion.update", "slack.post"],
  "approval": {"required": true, "decision": "approved", "actor": "user_42"},
  "executed_actions": [{"name": "notion.update", "idempotency_key": "..."}],
  "usage": {"platform_units": 812, "model_cost_usd": null},
  "status": "accepted"
}
Security and governance controls that change the decision
| Control | Required proof | Reject when |
|---|---|---|
| Identity and scope | Named service identity; narrow OAuth scopes; revocation tested | Only shared admin credentials work |
| Human approval | Server-side gate before irreversible or external side effects | Approval is merely a prompt instruction |
| Prompt-injection boundary | Untrusted content separated from instructions; side effects still gated | Web content can rewrite tool policy |
| Auditability | Exportable actor, input, tool, approval, output, and timestamp chain | Only a final chat transcript remains |
| Data lifecycle | Retention, deletion, residency, model-provider and sub-processor terms | Memory cannot be scoped or deleted predictably |
Compare cost per accepted task, not advertised units
accepted_task_cost =
  platform_subscription_allocated
  + model_and_tool_usage
  + retry_and_failed_run_cost
  + human_review_minutes × loaded_hourly_rate
  + operations_minutes × loaded_hourly_rate

acceptance_rate = accepted_tasks / attempted_tasks
effective_cost = total_period_cost / accepted_tasks
Run the same workload for at least two billing cycles or a representative batch. Credit systems, per-action systems, and direct model billing are not comparable until converted into accepted-task cost.
If you meant the historical LLM router, change the scorecard
An inference gateway should not be scored on CRM workflows or meeting behavior. It must preserve request contracts while routing across models, providers, keys, regions, and failure states.
Eight alternatives for the historical LLM routing intent
| Alternative | Best fit | Primary proof obligation |
|---|---|---|
| LiteLLM | Self-operated OpenAI-compatible gateway with broad provider coverage | Upgrade, database, virtual-key, budget, and fallback behavior under load |
| Portkey | Gateway plus routing, guardrails, observability, and managed control plane | Synchronous guardrail latency, streaming limits, policy portability |
| OpenRouter | Fast access to many models and providers with managed routing | Provider controls, fallback semantics, data policy, accounting reconciliation |
| Kong AI Gateway | Enterprise API governance extended to LLM, MCP, and A2A traffic | Plugin edition, deployment complexity, policy order, telemetry integration |
| Cloudflare AI Gateway | Edge-native analytics, caching, limits, and versioned dynamic routing | Route rollback, metadata policy, provider coverage, regional behavior |
| Vercel AI Gateway | AI SDK and Vercel application teams wanting unified models and routing | Provider options, rule propagation, non-Vercel portability, usage controls |
| Bifrost | Self-operated Go gateway with virtual-key governance and weighted routing | Deny-by-default configuration, model catalog sync, fallback ordering |
| Helicone | Unified gateway where provider routing and LLM observability are both central | Managed-key versus BYOK precedence, failure triggers, log and cost accuracy |
Keep a portable gateway adapter at the application boundary
import OpenAI from "openai";

type GatewayTarget = {
  baseURL: string;
  apiKey: string;
  model: string;
};

export async function runProbe(target: GatewayTarget, traceId: string) {
  const client = new OpenAI({ baseURL: target.baseURL, apiKey: target.apiKey });
  const started = Date.now();
  try {
    const response = await client.chat.completions.create({
      model: target.model,
      messages: [{ role: "user", content: "Return exactly: gateway-ok" }],
      temperature: 0
    });
    return {
      ok: response.choices[0]?.message?.content === "gateway-ok",
      model: response.model,
      usage: response.usage,
      latency_ms: Date.now() - started,
      trace_id: traceId
    };
  } catch (error) {
    return { ok: false, latency_ms: Date.now() - started, trace_id: traceId, error };
  }
}
The adapter makes base URL changes easy, but parity still depends on streaming, tools, structured output, error mapping, usage, timeouts, and provider-specific parameters.
Run the same contract suite against every gateway
| Test | Injection | Pass condition |
|---|---|---|
| Streaming | Long response with tool-capable model | Valid event order, terminal event, complete usage policy |
| Tool calls | Parallel and multi-turn tool request | IDs, arguments, roles, and continuation remain compatible |
| Fallback | 429, timeout, 500, invalid key, context overflow | Only approved failures trigger the expected next target |
| Policy | Disallowed model, tenant over budget, missing metadata | Deny before upstream call with stable error contract |
| Accounting | Success, retry, fallback, cache hit, partial stream | Gateway logs reconcile with provider invoice within tolerance |
Migration plan: map behavior before moving traffic
Inventory instructions, knowledge, memory, channels, connectors, credentials, schedules, approvals, human owners, side effects, run history, and retention rules. Rebuild one bounded workflow before attempting a fleet migration.
Inventory endpoints, SDKs, model aliases, provider keys, regions, fallbacks, retries, timeouts, rate limits, budgets, guardrails, logs, headers, errors, streaming, and tool-call contracts.
Canary rollout and rollback thresholds
- 1Shadow.Run the new path without side effects and compare normalized evidence.
- 2Internal canary.Use test identities, low-risk tasks, and explicit reviewer ownership.
- 3Limited production.Route a small segment with automatic rollback on safety or reliability thresholds.
- 4Expand only on evidence.Require stable acceptance rate, duplicate rate, latency, cost, and review burden.
Rollback if an unapproved side effect occurs; accepted-task rate drops by more than 5 percentage points; duplicate writes exceed 0.1%; p95 latency breaches the agreed SLO for two windows; or effective cost rises more than 20% without a documented quality gain.
Common failure modes buyers discover too late
| Failure mode | Detection | Control |
|---|---|---|
| Category mismatch | Team asks an LLM gateway to own business processes—or vice versa | Write the unit of work and owner before vendor selection |
| Approval exists only in prompts | Adversarial content causes an action without a server-side gate | Enforce approval outside the model loop |
| Duplicate side effects | Retry creates duplicate CRM, email, payment, or document writes | Idempotency keys and action receipts |
| Memory drift | Old assumptions override current source evidence | Scope, timestamp, expire, and cite memory |
| False gateway parity | Simple chat works but tools, streaming, usage, or errors diverge | Contract tests before traffic migration |
| Unreconciled cost | Platform usage does not match provider bills or accepted work | Daily reconciliation by run, model, provider, and outcome |
Where QVeris fits without pretending to replace either category
AI teammate platforms decide how work is planned and coordinated. LLM gateways decide how inference traffic reaches models. QVeris addresses a third layer: how an agent discovers, understands, and calls external capabilities without each tool becoming a bespoke integration.
- 1DiscoverSearch for a capability by intent and constraints.
- 2InspectReview the callable contract, inputs, outputs, and provider context.
- 3CallInvoke the selected capability through one controlled interface and retain evidence.
Explore QVeris only when capability discovery and external tool access are real requirements in your architecture.
Unify AI alternatives FAQ
What is the best Unify AI alternative?
It depends on which Unify you mean. For current AI teammate workflows, shortlist Lindy, Relevance AI, Microsoft Copilot Studio, and Glean Agents. For historical LLM routing intent, evaluate LiteLLM, Portkey, OpenRouter, Kong, Cloudflare, Vercel, Bifrost, and Helicone.
Is Unify still an LLM router?
The current Unify website presents AI teammates that perform ongoing work across tools and channels. Historical search results may still describe model routing, so buyers should separate those two categories before comparing products.
Which alternative is easiest for business workflow automation?
Lindy is a practical starting point for trigger-driven workflows, while Relevance AI emphasizes configurable agents and multi-agent workforces. Validate both with your own integrations, approvals, and failure cases.
Which alternative is strongest for Microsoft environments?
Microsoft Copilot Studio is the natural shortlist candidate when Microsoft 365, Power Platform, Teams, connectors, environments, and enterprise administration are already central to the organization.
Which alternative is strongest for enterprise knowledge governance?
Glean Agents deserves evaluation when enterprise search, permission-aware knowledge, governed actions, and administrator-controlled publishing are primary requirements.
What is the best self-hosted alternative for LLM routing?
LiteLLM, Kong, Portkey's open-source gateway, and Bifrost all offer self-operated paths with different operational footprints. Test upgrades, state stores, policy behavior, and observability before choosing.
Can I migrate by changing only the OpenAI base URL?
Sometimes for simple chat-completion traffic, but not for production parity. Streaming events, tool calls, model aliases, retries, errors, usage fields, authentication, and provider-specific parameters still need contract tests.
Where does QVeris fit?
QVeris is not a full replacement for an AI teammate or an LLM inference gateway. It complements either architecture by helping agents discover, inspect, and call external capabilities through one controlled interface.
Official sources and verification notes
Product behavior changes quickly. The links below are the primary-source baseline used for this guide; pricing, previews, limits, and enterprise terms should be rechecked during procurement.
- Unify current product, Unify official product information, Unify official product information, Unify official product information, and Unify official product information
- Lindy triggers and observability
- Relevance AI introduction and integrations
- Microsoft Copilot Studio overview
- Glean Agents and agent access controls
- LiteLLM, Portkey, OpenRouter, and Kong AI Gateway
- Cloudflare dynamic routing, Vercel provider options, Bifrost routing, and Helicone routing
Final decision rule
Choose an AI teammate when the vendor must own recurring work across people and tools. Choose an LLM gateway when your application owns the workflow and only inference access needs governance. Choose neither until the shared workload passes safety, reliability, cost, and rollback gates.